CI/CD Pipelines: Automating Software Delivery at Scale
Etsy famously reached a point where its engineers deployed to production over fifty times a day, not through heroics but through a pipeline that ran automated tests, built artifacts, and rolled changes out gradually with automated rollback if error rates spiked.
That level of deployment frequency is not a vanity metric, it is a direct consequence of investing in continuous integration and continuous delivery infrastructure that makes each individual change small, tested, and cheap to ship.
Most engineering organizations today run some version of a CI/CD pipeline, but the gap between a pipeline that merely runs tests on a pull request and one that reliably delivers software at scale is wide, and it is where a disproportionate amount of an engineering organization’s velocity is won or lost.
Continuous Integration Versus Continuous Delivery
Continuous integration refers to the practice of merging code changes into a shared branch frequently, with each merge automatically triggering a build and test run that verifies the change did not break anything.
The core discipline behind CI is catching integration problems early and cheaply, when engineers merge small changes multiple times a day rather than working in long-lived feature branches for weeks, the cost of resolving a conflict stays small, because the changes are small and feedback returns within minutes rather than after weeks of divergence.
Continuous delivery extends this further down the pipeline: not just verifying code builds and passes tests, but ensuring every change that passes is automatically packaged into a deployable artifact and kept ready to release at any time, even if the actual release still requires a manual approval step. Continuous deployment removes that manual gate entirely, so every change passing the pipeline deploys to production automatically, without a human deciding when each release happens.
The distinction between delivery and deployment matters practically because it reflects a real risk tolerance decision, not just terminology. A team handling financial transactions might deliberately stop at continuous delivery, keeping a human approval gate before production release, while a team running a lower-stakes tool with strong automated safety nets (canary analysis, automatic rollback on error-rate spikes) might reasonably run full continuous deployment, trusting the pipeline’s automated checks over manual judgment.
What unifies both practices is the underlying goal: reducing the batch size and manual toil involved in getting a change from a developer’s machine to users, since large, infrequent releases accumulate risk, make root-causing a regression harder, and create a psychological dread around releases that smaller, more frequent ones tend to dissolve as the process becomes routine.
Pipeline Stages: Build, Test, and Deploy
A typical CI/CD pipeline moves a change through a sequence of stages, each acting as a gate the change must pass before proceeding. The build stage compiles or packages the code, resolves dependencies, and produces an artifact, a container image, a compiled binary, immutable from that point forward, meaning the exact artifact that passes testing is the one that reaches production, rather than being rebuilt at each stage, which risks subtle differences creeping in.
The test stage typically runs in layers of increasing cost and decreasing speed: unit tests first, since they run in seconds and catch the largest volume of bugs cheaply; integration tests next, verifying components interact correctly against realistic dependencies; and end-to-end tests last, exercising the full system through interfaces closest to a real user, but running slowest and most brittle, so mature pipelines keep that suite intentionally small and focused on critical user journeys.
jobs:

test:

steps:

- run: npm ci

- run: npm run lint

- run: npm run test:unit -- --coverage

- run: npm run test:integration
Static analysis and security scanning frequently sit alongside the test stage, linters, type checkers, dependency vulnerability scanners like Dependabot or Snyk flagging known CVEs, and static application security testing tools looking for vulnerability patterns in source code, all running automatically on every change rather than as a periodic, separate audit.
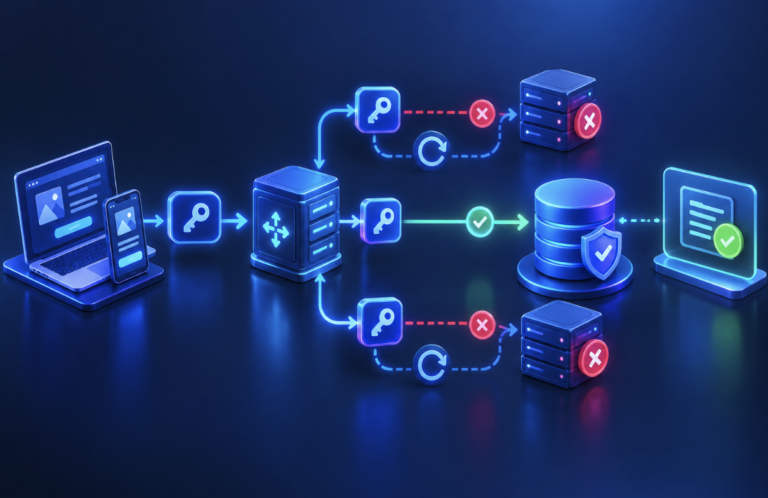
The deploy stage takes the validated artifact and releases it to one or more environments, typically staging first and production after further validation or approval. Mature pipelines treat this stage with the same rigor as earlier ones, using deployment strategies (discussed later) that limit blast radius, and automated health checks that trigger a rollback without waiting for a human to notice.
Platform Choices: Jenkins, GitHub Actions, and GitLab CI
Jenkins remains widely deployed, especially in larger, older organizations, because of its maturity, extensive plugin ecosystem, and flexibility to run on self-hosted infrastructure. That flexibility comes at a real cost: a team must maintain the Jenkins server itself, manage plugin compatibility across upgrades, and provision the build agents that execute pipeline steps, overhead newer, more managed platforms have designed away.
GitHub Actions has become a dominant choice for teams already hosting code on GitHub, integrating directly into the repository with no separate service to provision, using a YAML-based workflow syntax most engineers pick up quickly, and offering a large marketplace of pre-built actions that reduce how much pipeline logic a team writes from scratch. Its hosted runners remove infrastructure management entirely for most use cases.
GitLab CI offers a similarly integrated experience for teams using GitLab, with a strong built-in feature set spanning the full delivery lifecycle, registry hosting, security scanning, environment management, within a single connected platform, appealing to organizations wanting fewer distinct systems.
CircleCI, Travis CI, and cloud-native options like AWS CodePipeline round out the landscape, each with different trade-offs in pricing and cloud integration depth. The practical decision usually comes down less to which platform is objectively superior and more to where the code already lives.
Scaling Pipelines Across Large Monorepos
A monorepo housing dozens or hundreds of services and applications introduces a scaling problem that a small, single-service repository never faces: running the full test suite on every single change, regardless of what was touched, becomes prohibitively slow and expensive as the codebase grows, since a change to one small service’s code should not require rebuilding and retesting every unrelated service in the repository.
The standard solution is dependency-aware, incremental pipeline execution: tools like Bazel, Nx, and Turborepo build a dependency graph of the entire codebase and use it to determine precisely which packages are affected by a given change, running builds and tests only for those targets and their dependents, rather than the entire repository. This requires the codebase to have accurately declared dependencies, often a valuable engineering investment in its own right, since undeclared dependencies between packages silently produce false negatives, where a change breaks something the incremental pipeline never re-tested.
Caching compounds the benefit of this dependency-aware approach: once a package’s build or test output has been computed for a given set of inputs, remote caching systems (Bazel’s remote cache, Nx Cloud, Turborepo’s remote caching) let subsequent pipeline runs, and even other developers’ local builds, reuse that cached result instead of recomputing it, turning a pipeline that would take tens of minutes into one completing in a couple of minutes for changes touching only a small part of a large system.
Parallelization across pipeline stages and affected targets is the other major lever, splitting work across many concurrent workers rather than executing it sequentially, though this requires enough compute capacity to realize the benefit, and cost discipline to avoid the infrastructure bill growing unchecked as parallel jobs multiply.
Weighing Speed Against Safety in Deployment Gates
Every gate added to a pipeline, a required code review, a security scan, a manual approval step, a longer test suite, trades deployment speed for a reduction in the risk of a specific category of problem reaching production, and there is no universally correct balance point; the right trade-off depends on the actual cost of a production incident for the specific system in question.
A gate that takes twenty minutes to run and catches one significant bug a year might not be worth the cumulative delay it adds across thousands of deployments, while a gate that adds five minutes and reliably catches security vulnerabilities before they reach production is a straightforward, worthwhile cost for almost any team handling sensitive data.
Feature flags offer a way to partially decouple this trade-off: deploying code to production behind a flag that keeps it inactive lets a team ship code frequently and safely, satisfying the deployment-speed side, while still controlling exactly when and for whom a feature activates, satisfying the safety side separately from the deployment mechanism itself. This pattern, popularized broadly across the industry by tools like LaunchDarkly, effectively separates “is this code in production” from “is this feature live for users,” removing pressure from the deployment step.
Automated rollback based on real-time health signals is the other major safety lever: if a pipeline can detect, within a minute or two of a new version reaching a small fraction of traffic, that error rates or latency have degraded, and automatically roll back without waiting for a human to notice, the team can afford to move faster earlier in the pipeline because the safety net catches problems that slip through.
The organizations with the fastest, safest pipelines generally invest more in this kind of post-deployment safety net, canary analysis, automated rollback, feature flags, than in pre-deployment gates, because a fast, well-monitored rollback limits the blast radius of a bad change far more effectively than trying to catch every possible issue before it ships.
Typical Pipeline Failures and Root Causes
Flaky tests are the most corrosive recurring problem in CI/CD pipelines: a test that fails intermittently for reasons unrelated to the actual code change, a race condition in test setup, a dependency on wall-clock time, a shared resource contended by parallel test runs, trains engineers to re-run a failed pipeline rather than investigate it, and once that habit sets in, real failures start getting treated with the same “just re-run it” reflex, exactly how real regressions slip through a pipeline that looks rigorous but has quietly lost the team’s trust.
Long pipeline execution times produce a related but distinct failure mode: when a pipeline takes forty-five minutes, engineers batch up multiple changes before running it, or context-switch and lose track of a failure that occurred while focused elsewhere, both eroding the fast-feedback loop that is the entire point of continuous integration. Investing in caching, parallelization, and incremental execution is often the highest-leverage fix, more effective than simply adding compute to run the same slow pipeline faster.
Environment configuration drift between staging and production is another persistent source of failures that only manifest after deployment: a change passing every check in staging can still fail in production because of a configuration difference or a data volume difference staging’s smaller dataset never exercised, which is why infrastructure-as-code practices provisioning both environments from the same declarative templates reduce this surprise.
Secrets and credential management mistakes round out the most common failure category: hardcoding a credential in a pipeline configuration file, or granting a service account broader permissions than it needs, creates security exposure that often goes unnoticed until an audit surfaces it, which is why dedicated secrets tooling, GitHub Actions secrets, HashiCorp Vault, a cloud provider’s secrets manager, paired with least-privilege scoping, deserves the same attention as the pipeline’s functional logic.
Production Deployment Strategies: Canary, Blue-Green, and Rolling
Rolling deployment replaces instances of the old version with the new one gradually, a few at a time, rather than all at once, limiting the number of users affected if the new version has a problem and allowing automated health checks to halt the rollout partway through if error rates spike. This is the default strategy in Kubernetes Deployments and suits most stateless services, though for a period both old and new versions serve traffic simultaneously, requiring the two to remain compatible, especially around shared resources like a database schema.
Blue-green deployment takes a different approach: maintaining two complete, identical production environments, only one of which actively receives traffic at any time, while the new version is deployed and validated in the idle environment before traffic switches over, typically instantly, at the load balancer level. This gives a fast, clean rollback path, switching traffic back, but at roughly double the infrastructure cost during the deployment window.
Canary deployment routes a small percentage of production traffic, often starting at one or five percent, to the new version while the majority continues to hit the stable version, then gradually increases that percentage as confidence grows, based on automated comparison of error rates, latency, and other key metrics between the canary and the baseline. This approach, popularized by Google’s internal deployment practices and now widely supported by tools like Argo Rollouts and Flagger in Kubernetes environments, gives the most granular control over blast radius and the earliest possible detection of a problem, since only a small fraction of real users are exposed before the deployment either proceeds or gets automatically rolled back.
Choosing among these strategies depends on the system’s tolerance for running two versions simultaneously, its infrastructure budget for redundant environments, and how much automated observability exists to make a canary’s gradual rollout truly safer than a straightforward rolling deployment, a canary strategy without solid automated metrics comparison provides little real benefit over a simpler rolling deployment, since the whole value of canary analysis depends on quickly and reliably detecting a regression in the small slice of traffic it exposes.
Building a Pipeline from Scratch
Starting a CI/CD pipeline for a project that has none begins most productively with the test stage, not the deployment stage: getting automated tests running reliably on every pull request, with results visible directly in the code review interface, delivers immediate value by catching regressions before merge, and establishes the habit of treating a red pipeline as something that blocks a merge rather than something to notice later.
Layering in the build and artifact stage next, ensuring the exact artifact that passes testing is the one that eventually reaches production rather than something rebuilt separately at deploy time, closes a surprisingly common gap where “it passed tests” and “what’s running in production” turn out to be subtly different builds due to a dependency resolving differently or an environment variable changing between build environments.
Deployment automation should start targeting a staging environment before production, giving the team confidence in the pipeline’s mechanics, does the deploy step work reliably, do health checks correctly detect a bad deployment, in an environment where mistakes carry a far lower cost than in production, before extending the same automated deployment path to production with an initial manual approval gate that can be removed later as confidence grows.
From there, adding progressively more sophistication, incremental builds if the codebase is large enough to benefit, a canary or blue-green deployment strategy once the team has the observability infrastructure to make it truly useful, and automated rollback triggered by health signals, should follow the actual pain points the team experiences, rather than being adopted wholesale from a reference architecture that may not match the specific system’s scale, risk profile, or team size, since a pipeline built for a company with hundreds of engineers is often substantial over-engineering for a five-person team, and vice versa.
Final Thoughts
A CI/CD pipeline’s real value is measured by how much it shrinks the distance between writing code and knowing, with confidence, that it works correctly in production, and every stage added should earn its place by reducing risk proportionally to the delay it introduces.
Teams that treat pipeline design as a continuous investment, fixing flaky tests promptly, scaling test execution as the codebase grows, and layering in safer deployment strategies as observability matures, end up able to ship frequently and safely, which is the real goal behind the discipline.
Frequently Asked Questions
1. What is the difference between continuous delivery and continuous deployment?
Continuous delivery means every change that passes the pipeline is automatically packaged and ready to release, but a human decides when to deploy it to production. Continuous deployment removes that manual step entirely, deploying every passing change to production automatically without a human gate.
2. How long should a CI pipeline take to run?
There is no universal target, but pipelines that take longer than roughly ten to fifteen minutes tend to erode the fast-feedback benefit that motivates continuous integration in the first place, since engineers start batching changes or context-switching away rather than waiting for immediate results.
3. What causes flaky tests, and how should teams handle them?
Common causes include race conditions in test setup, dependencies on timing or execution order, and shared state between parallel test runs. Flaky tests should be fixed or quarantined promptly rather than tolerated, since a pipeline engineers do not trust gets its failures ignored, including real ones.
4. Is Jenkins still a reasonable choice for a new project?
For teams needing extensive self-hosted control, custom plugins, or specific compliance requirements, Jenkins remains viable. For most new projects, especially those already hosted on GitHub or GitLab, the tightly integrated, lower-maintenance platforms those hosts offer natively are usually a faster path to a working pipeline.
5. What is a canary deployment, and when is it worth the added complexity?
A canary deployment routes a small percentage of production traffic to a new version before a full rollout, detecting problems early with minimal user impact. It is worth the added complexity primarily when a team has solid automated metrics comparison to make the canary phase meaningful, rather than just a slower rolling deployment in disguise.
6. How does a monorepo change CI/CD pipeline design?
A monorepo requires dependency-aware, incremental pipeline execution to avoid rebuilding and retesting the entire codebase on every change. Tools like Bazel, Nx, or Turborepo build a dependency graph and run builds and tests only for the packages affected by a given change, along with their dependents.