Idempotency in API Design: Building Safe, Retry-Proof Requests
A payment gets submitted, the customer’s network connection flickers right at the critical moment, and their phone shows a spinning loading icon with no confirmation either way. Uncertain whether the payment actually went through, they tap the button again. If the underlying system wasn’t built with this exact scenario in mind, that customer just got charged twice for a single purchase.
What Idempotency Actually Means
Idempotency refers to an operation’s property of producing the same result regardless of how many times it gets performed, meaning executing the same request multiple times has the same effect as executing it exactly once. In the context of APIs specifically, this means a client can safely retry a request without worrying about unintended, duplicate side effects like our double-charged customer above.
This safety property matters enormously for building reliable systems, given that network failures, timeouts, and other communication problems are simply an unavoidable part of distributed systems, making the ability to safely retry requests without unintended consequences an essential design consideration rather than an optional nicety.
Why Network Unreliability Makes Idempotency Necessary
Network requests can fail, time out, or leave clients uncertain whether a request actually succeeded. Without idempotency, retrying an uncertain request risks duplicating whatever action that request was meant to perform. This uncertainty is a fundamental, unavoidable characteristic of distributed systems communicating over unreliable networks, not simply an occasional edge case.
A client that submits a payment request and never receives a clear response cannot tell whether the request failed before reaching the server, succeeded but the response got lost on the way back, or is still processing. Without idempotency, safely resolving this uncertainty through a simple retry becomes impossible, exactly the bind our flickering-connection customer found themselves in.
Which HTTP Methods Are Naturally Idempotent by Design
GET requests, which simply retrieve data, are naturally idempotent since repeating them doesn’t change anything. PUT requests, which set a resource to a specific state, are typically idempotent since setting the same state repeatedly produces the same result. POST requests, commonly used for creating new resources, are notably not naturally idempotent, since submitting the same creation request twice typically creates two separate resources, exactly the double-payment problem this whole discussion centers on.
How Developers Actually Make Non-Idempotent Operations Safe to Retry
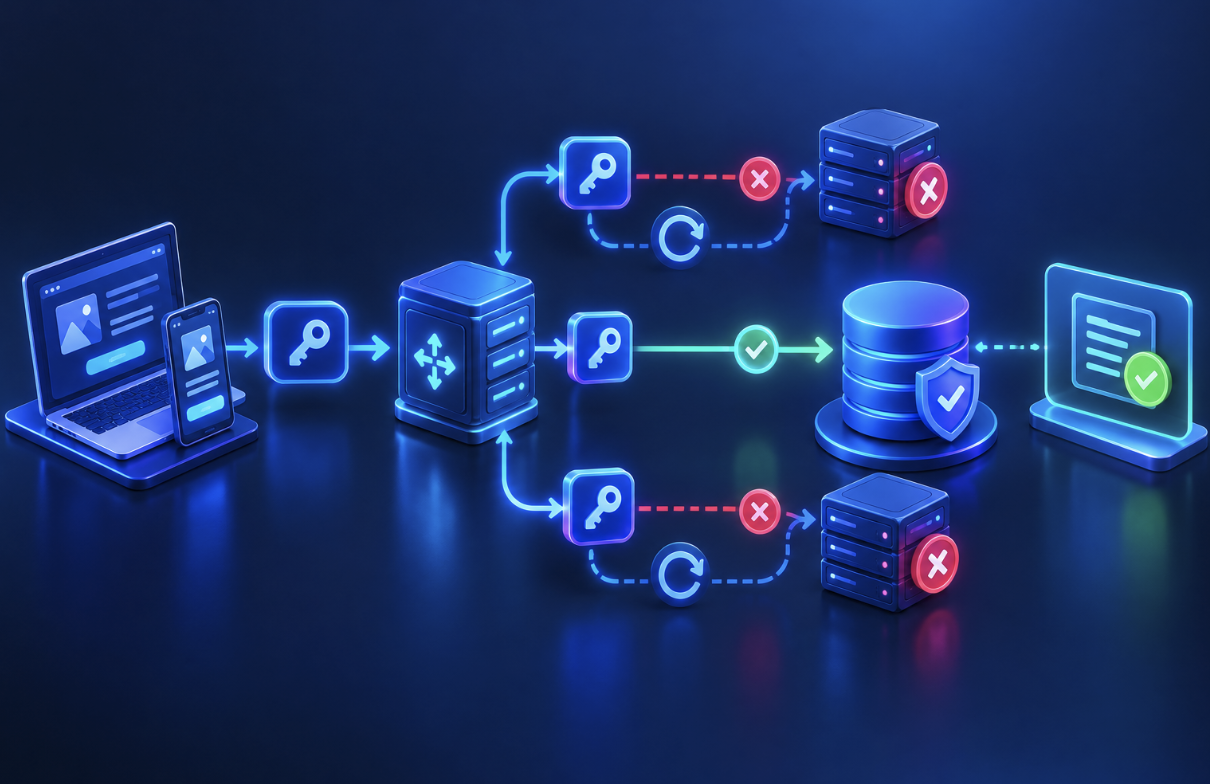
A common technique involves having clients generate a unique identifier for each logical operation, then having the server check whether it has already processed a request with that specific identifier before actually executing it again. If the server recognizes the identifier as already processed, it simply returns the original result rather than repeating the underlying action.
This idempotency key approach deserves particular emphasis, since it specifically transforms naturally non-idempotent operations, like creating a payment, into operations that are safe to retry, letting clients confidently resend a request without fear of duplicating an action, precisely because the server can now recognize and deduplicate against a previous identical attempt using that shared identifier.
Why Payment Systems Take Idempotency Particularly Seriously
Payment processing represents one of the clearest, highest-stakes examples of where idempotency matters, given the real financial consequences duplicate transactions would cause. Major payment processors typically require or strongly encourage idempotency keys specifically for this reason. Understanding this pattern helps explain why payment APIs specifically emphasize idempotency documentation so prominently compared to many other types of APIs.
How Idempotency Affects Broader System Design Decisions
Building idempotent operations into a system often requires additional design consideration beyond simply implementing the core business logic. Systems need mechanisms for tracking which operations have already been processed. This additional design requirement represents a genuine, worthwhile trade-off given the reliability benefits idempotency actually provides.
Challenges Implementing Idempotency Presents
Determining appropriate scope and duration for tracking processed requests requires careful consideration. Storing idempotency tracking data introduces its own additional infrastructure requirements. Teams need to balance idempotency guarantees against the additional complexity and infrastructure this capability requires.
What Would Have Happened to Our Customer With Proper Idempotency in Place
Returning to that flickering connection and the anxious double-tap, a properly idempotent payment API would have handled this gracefully. The client would have generated a unique idempotency key for that specific payment attempt before sending the request. When the customer tapped again, uncertain whether the first attempt succeeded, the retry would have carried that same key, and the server would have recognized it as already processed, simply returning the original confirmation rather than charging the customer a second time.
This is precisely the safety net idempotency provides, turning a genuinely anxious, uncertain moment for the customer into a technical non-event handled invisibly by infrastructure specifically designed for exactly this scenario.
How Idempotency Keys Actually Get Generated and Managed in Practice
Client applications typically generate idempotency keys using techniques that guarantee uniqueness, commonly relying on randomly generated identifiers specifically designed to avoid any realistic possibility of collision between genuinely separate, unrelated requests. The client includes this generated key within the request, and the server maintains a record associating that specific key with the eventual result of processing that request the first time it actually occurs.
Server-side management of these keys requires, careful consideration regarding storage duration and cleanup. Keeping every idempotency key indefinitely would accumulate unbounded storage requirements over time, while removing keys too quickly risks losing the protection idempotency is meant to provide if a client’s retry arrives after the tracking record has already been cleaned up. Most systems settle on a reasonable retention window, often covering a day or more, balancing realistic retry scenarios against practical storage constraints.
Why Idempotency Interacts Closely With Distributed System Design More Broadly
Idempotency becomes considerably more technically challenging to implement correctly within distributed systems, where the server handling an initial request and the server handling a subsequent retry might actually be entirely different physical machines within a load-balanced infrastructure. This means idempotency key tracking typically can’t simply live in one server’s local memory, but instead needs to exist within shared, centrally accessible storage that any server instance can consult regardless of which specific instance originally processed the request.
This distributed storage requirement connects idempotency implementation directly to broader distributed systems concepts discussed elsewhere, including the trade-offs around consistency and availability that shared, centrally accessible storage across a distributed system inevitably involves.
A system’s specific approach to idempotency key storage often reveals quite a bit about its broader underlying architecture and the particular consistency guarantees that architecture has been designed to provide.
How Idempotency Differs Across Different Types of Operations
Not every operation benefits equally from idempotency protection, and understanding these differences helps teams prioritize where to actually invest implementation effort. Operations with irreversible real-world consequences, like charging a payment or sending an email, warrant particularly careful idempotency implementation, given the real cost of getting this wrong. Operations that are naturally more forgiving of occasional duplication, like logging a non-critical analytics event, may not justify the same rigorous implementation effort.
This prioritization matters because implementing robust idempotency across every single operation within a large system represents real, ongoing engineering investment, meaning teams benefit from honestly assessing which specific operations actually carry consequences serious enough to justify that investment, rather than treating idempotency as a uniform requirement applied identically and indiscriminately across an entire system regardless of each operation’s actual real-world stakes.
How Idempotency Testing Actually Differs From Testing Ordinary Application Logic
Verifying that an operation behaves idempotently requires a specifically different testing approach compared to typical functional testing, since the goal isn’t simply confirming an operation produces the correct result once, but rather confirming that repeating the same operation multiple times, potentially with realistic timing variations between attempts, still produces exactly that same correct result without unintended side effects accumulating.
Thorough idempotency testing typically involves deliberately simulating the kinds of failure scenarios idempotency is meant to protect against, like interrupting a request partway through processing and then retrying it, or sending duplicate requests with matching idempotency keys in rapid succession to confirm the system correctly recognizes and deduplicates them.
Teams that skip this specific kind of deliberate failure-scenario testing sometimes discover their idempotency implementation contains subtle bugs only once a genuine production incident actually exercises the exact edge case their testing never specifically covered.
Why Idempotency Alone Doesn’t Solve Every Reliability Problem a Distributed System Faces
It’s worth being clear that idempotency specifically addresses the problem of safely retrying uncertain requests, but doesn’t by itself guarantee an operation will actually succeed, nor does it address other reliability concerns like ensuring a request actually reaches its destination in the first place. Idempotency works alongside other reliability patterns, including the retry logic and circuit breaker patterns discussed elsewhere, rather than functioning as a complete, standalone reliability solution on its own.
Teams sometimes mistakenly treat idempotency implementation as though it single-handedly solves distributed systems reliability, when it more accurately represents one important piece within a considerably broader reliability strategy that also needs to address concerns like detecting failures, implementing appropriate retry timing, and gracefully handling situations where an operation cannot succeed despite repeated attempts.
Understanding idempotency’s specific, bounded scope within this broader reliability picture helps teams avoid both underinvesting in this genuinely important pattern and mistakenly treating it as a complete solution to problems it was never actually designed to address on its own.
How Idempotency Considerations Differ Between Internal and Public-Facing APIs
Internal APIs, used only by services within an organization’s own control, often warrant somewhat different idempotency considerations compared to public-facing APIs consumed by external developers whose retry behavior an organization cannot directly control or predict. Internal teams can coordinate more closely around specific retry patterns and timing, while public APIs need to accommodate a considerably wider, less predictable range of client implementation choices and retry behaviors.
This distinction matters for how thoroughly a team should document and test their idempotency implementation, since public-facing APIs need documentation clear and thorough enough for external developers, who have no direct access to internal implementation details, to correctly understand exactly how to use idempotency keys properly within their own applications.
Internal APIs can sometimes rely more heavily on direct communication and shared organizational knowledge, though even internal systems benefit from clear documentation as an organization grows and institutional knowledge becomes harder to maintain purely through informal channels alone.
Final Thoughts
Idempotency provides essential protection against the duplicate actions that network unreliability and client uncertainty can otherwise cause, particularly critical for operations with real, meaningful consequences like payment processing. For that anxious customer staring at a spinning loading icon, a properly idempotent system is precisely what stands between a minor moment of uncertainty and a frustrating billing dispute.
Frequently Asked Questions
1. Do all API operations need to be idempotent?
No, not every operation requires this property, though operations with real-world consequences from duplication, particularly financial transactions, benefit significantly from idempotent design.
2. How long should a server typically retain idempotency key records?
This varies by specific use case, though many systems retain records for a period reasonably covering realistic retry windows, balancing safety against the storage costs of retaining this tracking data indefinitely.
3. Can idempotency be added to an existing API after the fact?
Yes, though this typically requires additional development work to implement idempotency key handling and tracking, making it somewhat more involved than building this consideration in from the very beginning of a system’s design.
4. Does idempotency guarantee an operation will succeed?
No, idempotency specifically addresses what happens when the same operation gets attempted multiple times, not whether the underlying operation itself will actually succeed on any given individual attempt.
5. Are idempotency keys required by law for payment processing?
Requirements vary by jurisdiction and specific payment processor, though many major processors strongly encourage or require this practice as a matter of their own technical standards and risk management, regardless of specific legal requirements.
6. Can GET requests have side effects that break their natural idempotency?
Technically yes, if implemented poorly, though this violates the intended, expected semantics of GET requests, meaning well-designed APIs avoid this and keep GET requests properly idempotent as expected.