Idempotency in API Design and Why It Prevents Costly Errors
In 2015, an engineer at a payments company described a production incident where a mobile client, on a flaky cellular connection, retried a failed checkout request four times before one response finally made it back to the device, and the backend, having no way to recognize the retries as the same logical operation, charged the customer’s card four times.
The fix was not better network handling on the client; it was making the charge endpoint idempotent, so retrying the same request produced the same result without duplicating the side effect. This is the kind of bug idempotency exists to prevent.
Defining Idempotency Through HTTP Semantics
Idempotency, in the formal sense used by the HTTP specification, means that making the same request multiple times produces the same result as making it once, the operation’s side effects do not accumulate with repetition.
GET, PUT, and DELETE are defined as idempotent by the HTTP spec: fetching a resource repeatedly does not change it, replacing a resource with the same representation leaves it in the same final state, and deleting an already-deleted resource is still “deleted” after the second attempt, even if the server returns a 404. POST is explicitly not idempotent by default, since it is conventionally used to create a resource or trigger a side effect meant to occur once per call, submitting a form, charging a card, sending an email.
This distinction matters enormously for retry logic. HTTP clients, browsers, proxies, and libraries are generally safe to retry automatically on GET requests when a network error occurs, because idempotency guarantees the retry cannot cause harm beyond redundant reads. The same automatic retry behavior applied blindly to a POST request is exactly what caused the quadruple-charge incident described above, the client could not tell whether the first attempt had succeeded on the server before the response was lost, and retrying blindly assumed it had not.
It is worth being precise that idempotency is about the end state of the operation, not whether the server does identical work each time. A PUT request that sets a user’s email address to “new@example.com” is idempotent even though the underlying database write happens on every call, because the resulting state is the same regardless of how many times the request is repeated. This differs from a POST request that increments a counter or appends a row to a table, where each successful call changes the end state further.
Many real-world APIs blur this line deliberately for convenience, a POST endpoint that creates a resource might be made effectively idempotent by accepting a client-supplied identifier and returning the existing resource if that identifier has already been used, rather than creating a duplicate. This pattern, formalized through the idempotency key, is how most modern APIs solve the problem of needing POST-like semantics (creating something, charging something) with the safety guarantees of idempotent retries.
Idempotency Keys and How They Prevent Duplicate Charges
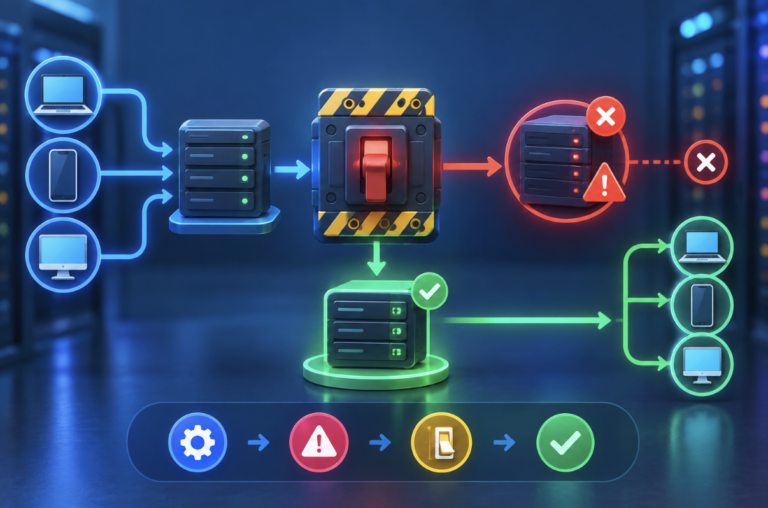
An idempotency key is a unique identifier, typically a UUID generated by the client, sent with a request that the server uses to detect and deduplicate retries. Stripe’s implementation is the most widely referenced in the industry: a client generates a key once per logical operation, once per checkout attempt, not once per HTTP request, and includes it in an `Idempotency-Key` header. If the server has already processed a request with that key, it returns the cached result rather than executing the charge again, however many times the client retries.
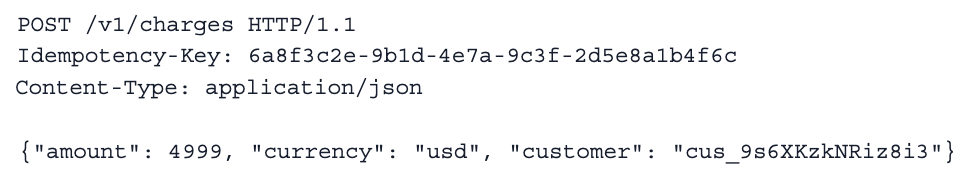
The server-side implementation generally stores each idempotency key alongside the request payload’s hash, the response, and the status of the operation (in progress, succeeded, failed), typically with a time-to-live of twenty-four hours or a few days, long enough to cover realistic retry windows without keeping the deduplication table growing indefinitely.
When a request arrives with a key that is already stored, the server compares the incoming request payload against the stored hash, if they match, it returns the cached response; if they do not match, it typically returns an error, since a mismatched payload with a reused key usually indicates a client bug rather than a legitimate retry.
A subtlety that trips up many implementations is handling concurrent requests with the same key that arrive before the first one has finished processing, a client that retries too aggressively, before the original request timed out on its end, can trigger a race condition where two requests both see “no existing record” and both proceed to execute the operation.
Correct implementations lock on the idempotency key for the duration of the first request, returning a 409 Conflict or making the second request wait, rather than allowing both to proceed and rely on database constraints to catch the duplication after the fact, which is a much weaker guarantee under concurrent load.
Designing Idempotent Endpoints for Payments and Orders
Payment and order-creation endpoints are the canonical use case for explicit idempotency, because the cost of a duplicate side effect is direct financial harm to a customer, and because network unreliability between client and server is a fact of life that no amount of infrastructure investment fully eliminates.
A well-designed charge endpoint requires the idempotency key as a mandatory parameter rather than an optional one, since an optional idempotency key is one that engineers under deadline pressure will frequently forget to pass, defeating the protection entirely.
Order-creation endpoints face a related but distinct challenge: the operation is not just “did this transaction happen” but “does this order already exist,” and a well-designed system deduplicates on business-meaningful keys in addition to, or instead of, a client-generated idempotency key. An e-commerce checkout might deduplicate on a combination of customer ID, cart contents hash, and a time window, catching duplicates even if the idempotency key mechanism failed or was bypassed by a buggy integration.
The response returned for a duplicate request deserves as much design attention as the original success response. Returning the exact same response body and status code the client would have received from the original successful request, not a generic “duplicate detected” error, lets client code handle the idempotent retry path identically to the success path, without needing special-case logic to distinguish “this succeeded just now” from “this succeeded a moment ago and you’re seeing the cached result.”
A frequently overlooked detail is that idempotency needs to extend through the entire chain of operations a request triggers, not just the primary database write. A charge endpoint that correctly deduplicates the payment record but calls a downstream email service or a fulfillment queue outside the idempotency-protected transaction can still send a duplicate confirmation email or trigger a duplicate shipment, even though the financial charge itself was correctly protected, which is why idempotency should be designed around the full set of side effects a request causes, not just the one that is easiest to protect.
Contrasting Idempotency Approaches Across REST and Message Queues
REST APIs typically implement idempotency through the mechanisms already described: relying on the inherent idempotency of PUT and DELETE, and adding explicit idempotency keys to POST endpoints that need the same guarantee. The request-response model makes this relatively straightforward, since the client controls exactly when a retry happens and can attach the same key to each attempt.
Message queues and event-driven systems face a related but structurally different problem, because most queue systems, Amazon SQS, RabbitMQ, Kafka in certain consumer configurations, provide at-least-once delivery rather than exactly-once, meaning a consumer can receive and process the same message more than once, not from a client retry, but because of the queue’s own internal failure-recovery mechanics, such as a consumer crashing after processing a message but before acknowledging it.
Idempotency in this context is usually implemented at the consumer level: the message carries a unique identifier (often the same idempotency key concept, generated at message production time), and the consumer checks a deduplication store, a Redis set with a TTL, or a unique constraint in a relational table, before processing, skipping messages it has already handled.
Kafka’s exactly-once semantics, introduced in later versions, reduces but does not eliminate the need for this pattern, since exactly-once guarantees within Kafka’s own transactional boundaries do not automatically extend to side effects the consumer produces outside Kafka, like calling an external payment API.
The practical difference engineers should internalize is that REST idempotency is usually opt-in, added deliberately to specific endpoints that need it, while queue-based idempotency is closer to a baseline requirement for any consumer that has side effects, since at-least-once delivery is the norm rather than the exception across most managed queue systems, and treating message consumption as if it were exactly-once by default is a common and costly mistake.
Trade-Offs in Storage and Expiry of Idempotency Records
Storing idempotency records indefinitely is rarely the right choice, since the storage grows unbounded and most legitimate retry scenarios resolve within seconds to hours, not months. Stripe’s approach of a twenty-four-hour retention window reflects a reasonable industry default: long enough to cover retries from a client that was offline for an extended period, short enough to keep the deduplication table’s size and query performance manageable over time.
The storage backend choice involves its own trade-offs. A relational table with a unique constraint on the idempotency key is simple to reason about and integrates naturally with the same transaction performing the underlying operation, letting the check and the business logic commit or roll back together atomically.
Redis, with its native TTL support, is a common alternative for high-throughput systems where a relational transaction for every check would add unacceptable latency, at the cost of losing strong consistency guarantees, a Redis-based implementation needs its own care to avoid race conditions during the check-and-set operation.
A trade-off easy to underestimate is what to do when the idempotency store itself is unavailable. If a Redis instance holding idempotency keys goes down, does the system fail closed, rejecting requests until it recovers, or fail open, processing requests without deduplication but risking duplicate side effects? Payment systems generally fail closed, a temporary outage in idempotency checking is a smaller cost than double-charging customers.
Recurring Bugs from Missing Idempotency Guarantees
The most common bug pattern is assuming that a database’s unique constraint alone provides sufficient idempotency protection, without considering the window between a client’s first request timing out and a legitimate retry arriving. A unique constraint on an order ID prevents a true duplicate insert, but if the first request is still in flight, the database write has not happened yet, a fast retry can race ahead of it, and depending on transaction isolation level, both requests can pass a “does this exist” check before either has committed, defeating the constraint’s protection.
A second recurring bug involves partial failure inside a multi-step operation lacking proper idempotency boundaries: an endpoint that charges a customer, writes an order record, then triggers a fulfillment event, where the charge succeeds but the order write fails due to an unrelated database issue. A naive retry re-executes the entire endpoint, charging the customer a second time, because the key was checked against the whole endpoint’s completion rather than each individual step.
Client-side bugs are just as common: generating a new idempotency key on every retry attempt, rather than reusing the same key for the same logical operation, defeats the mechanism entirely, since the server has no way to recognize the retries as related. This often creeps in when keys are generated inside a function called again on retry, rather than once at the start of the user’s action and threaded through every attempt.
Finally, teams frequently fail to test idempotency behavior under real concurrent load, verifying only that a single retry works correctly in a manual test, while the production failure mode that causes harm is near-simultaneous concurrent requests racing against each other during a network timeout, a scenario that requires deliberate load testing with concurrent identical requests to catch before it reaches production.
Real-World Examples from Stripe and AWS
Stripe’s idempotency implementation is widely cited as the reference design in the industry, partly because payments make the stakes so concrete, and partly because Stripe’s public documentation explains the mechanism in enough detail that other companies have modeled their own APIs on it. Stripe requires the idempotency key on mutating requests where duplication would be costly, caches the full response for replay, and documents the request-hash-mismatch error case, giving integrators a clear contract to build retry logic against rather than reverse-engineering the behavior.
AWS provides idempotency support across several services tailored to each service’s semantics. DynamoDB’s conditional writes, using a condition expression that checks whether an item already exists before writing, give a low-level building block for idempotent writes. Lambda, when integrated with SQS or other at-least-once sources, expects functions written idempotently since AWS documents that a function can be invoked more than once for the same event, placing the burden of deduplication on the function’s logic or an external store like DynamoDB.
Amazon’s EC2 API also uses client-provided idempotency tokens on operations like `RunInstances`, specifically to prevent a network timeout during instance launch from accidentally provisioning duplicate infrastructure, a scenario with real financial cost, since duplicate instances mean paying for compute capacity that was never intended to exist.
Implementing Idempotency in Your Own APIs
Getting started requires deciding which endpoints need explicit idempotency protection, generally, any endpoint that creates a resource, moves money, or triggers an external side effect like sending an email or a notification, while pure read endpoints need no additional work since GET is already idempotent by nature.
Retrofitting idempotency onto an existing API without breaking backward compatibility usually means adding the idempotency key as an optional header initially, with clear documentation encouraging clients to adopt it, before eventually making it mandatory once client libraries have been updated.
The deduplication store needs a schema that captures at minimum the key itself, a hash of the request payload, the response to replay, a status field distinguishing in-progress from completed operations, and a creation timestamp for expiry. Wrapping the idempotency check and the underlying business logic in the same database transaction, where the technology allows it, is the most reliable way to avoid the race conditions described earlier, since it ensures the idempotency record and the actual side effect either both commit or both roll back together.
Client libraries should generate the idempotency key once per logical user action and persist it locally until the operation is confirmed complete, rather than regenerating it on every retry attempt, for a checkout flow, this typically means generating the key when the user clicks “submit,” storing it in memory or local storage, and reusing it across every retry until a definitive success or failure response is received. Finally, testing should include explicit scenarios for concurrent identical requests and for requests with the same key but a different payload, since both are realistic production scenarios that a simple “does the happy path retry work” test will not catch.
Final Thoughts
Idempotency is not an edge case to handle later; it is a design decision that determines whether network failures, which are guaranteed to happen at scale, produce safe retries or costly duplicated side effects.
The mechanism itself, a client-generated key, a server-side deduplication store, a defined expiry window, is straightforward to implement once a team commits to it, and the cost of skipping it shows up unpredictably, exactly when a retry collides with a slow response. Treating idempotency as a first-class part of API design is one of the highest-leverage habits a backend team can adopt.
Frequently Asked Questions
1. Is idempotency the same as being stateless?
No, these are different concepts entirely. Statelessness means the server does not rely on session state between requests. Idempotency means that repeating the same request produces the same result without additional side effects. An API can be stateless without being idempotent, and idempotency generally requires some server-side state, the deduplication record, to enforce.
2. Which HTTP methods are idempotent by default?
GET, PUT, DELETE, HEAD, OPTIONS, and TRACE are defined as idempotent by the HTTP specification. POST and PATCH are not idempotent by default, since they are conventionally used for operations, like creation or partial updates, where repeating the exact request could reasonably produce a different or additional effect.
3. How long should an idempotency key remain valid?
There is no universal answer, but twenty-four hours is a common industry default, long enough to cover realistic client retry windows including temporary outages, while keeping the deduplication store from growing without bound. Systems with longer expected offline periods for clients may extend this window.
4. What happens if two requests use the same idempotency key with different payloads?
Well-designed APIs treat this as an error condition, since it typically indicates a client bug rather than a legitimate retry, and returning an explicit error surfaces the problem during development rather than silently processing one of the two conflicting requests and discarding the other.
5. Do idempotency keys need to be globally unique?
They need to be unique within the scope the server checks them against, which is usually per API key, per customer, or per endpoint rather than globally across the entire system. UUIDs are the most common choice because their collision probability is low enough to treat as effectively unique in practice.
6. Can idempotency fully eliminate duplicate side effects?
It substantially reduces the risk but requires the deduplication logic to cover every side effect the operation triggers, not just the primary database write. Downstream calls to email services, webhooks, or other systems made outside the idempotency-protected transaction boundary can still duplicate unless they are explicitly included in the same protection.